Overview
Suppose an agent answering from retrieved sources collects irrelevant documents and returns an incorrect answer. Several changes are possible without changing model weights: revise the instructions for writing search queries, separate retrieval and answering into different calls, implement a check on search results, or reuse a previously successful search procedure.
A harness is the surrounding system that puts a model to work, including the instructions and information it receives, tools, call order, and state retention. Harness optimization uses execution results and evaluations to change this system and search for configurations that solve problems better. This book compares related research ranging from prompt optimization to improvements in workflows, code, and memory.
The basic process uses execution records to propose harness changes, compares them with the current version, and carries accepted changes forward to subsequent inputs. The optimizer is the entire procedure, including evaluation and selection, not just candidate generation.
Revising One Answer Versus Changing How Problems Are Solved
The key questions are what gets updated and what remains to solve subsequent problems.
Critiquing and rewriting the solution to a mathematical problem improves the answer to that problem. In contrast, rewriting shared instructions from incorrect answers to multiple training problems, then applying the same instructions to unused problems, changes the problem-solving system. ProTeGi edits instructions using classification errors, while MIPRO searches over instructions and demonstrations for multiple model calls (Pryzant et al. 2023; Opsahl-Ong et al. 2024).
The same distinction applies to code. Fixing a program delivered to a user differs from fixing the tools or control logic of the agent that writes programs. ADAS and DGM include the latter in their search spaces (Hu et al. 2025; Jenny Zhang et al. 2026).
Figure 1 illustrates this boundary by contrasting it with model training. In the AgentOptimizer figure, “Update Functions” means updating the functions an agent uses, not the numerical parameters of the target model (S. Zhang et al. 2024).
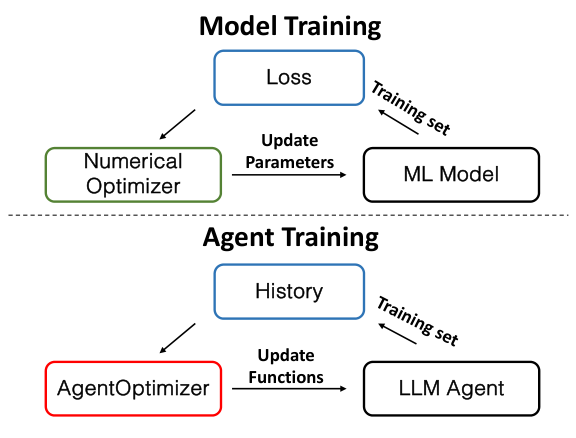
The book centers on research that fixes the target model’s weights and improves an external system used across multiple inputs. It does not, however, exclude related work solely for failing to meet this condition. Methods that generate a workflow for each input or update model weights are also compared, with their similarities and differences made explicit.
Instructions, Logic, and Procedures Retained from Experience
Consider illustrative changes that could follow from the retrieval failure at the start.
| Retained Change | What Changes for the Next Input | What the Change Alone Does Not Establish |
|---|---|---|
| An instruction to include a person’s name and a date range in search queries | The queries generated by the model | Whether the necessary documents are actually retrieved |
| An added evidence-checking step after retrieval | The order and number of calls | Whether the check is worth its cost |
| An implementation that does not answer when search results are empty | The action chosen for a particular failure | Whether it also works on other inputs |
| A previously successful search procedure | The experience consulted next | Whether it transfers to a new task |
These examples are not measured results from particular papers. They make the unit of comparison concrete. Actual studies differ in their editable representations and evaluations. GPTSwarm works with graphs of model calls, AFlow with workflows expressed in code, and ExpeL with insights extracted from experience (Zhuge et al. 2024; Jiayi Zhang et al. 2025; Zhao et al. 2024). Describing all of them as merely “improving prompts” obscures differences in the changes they can search over.
Conversely, different representations may share the same limitation. Repeatedly fitting either instructions or code to evaluation inputs can produce high scores only on those inputs. Broad editing freedom and improvement on unseen problems are different properties.
Separating the Candidate Generator from the Entire Optimizer
A model that writes proposed revisions as text or code is a candidate generator. In this book, the optimizer is the entire procedure, including candidate generation, execution, evaluation, selection, and updates to the search history.
Figure 2 is an original-paper figure that helps separate three components. The left shows the range of expressible candidates, the middle the procedure for searching that range, and the right the criterion for scoring candidates. Making code editable changes the left component. Changing how the next candidate is chosen changes the middle. Changing evaluation problems is different from either (Hu et al. 2025).
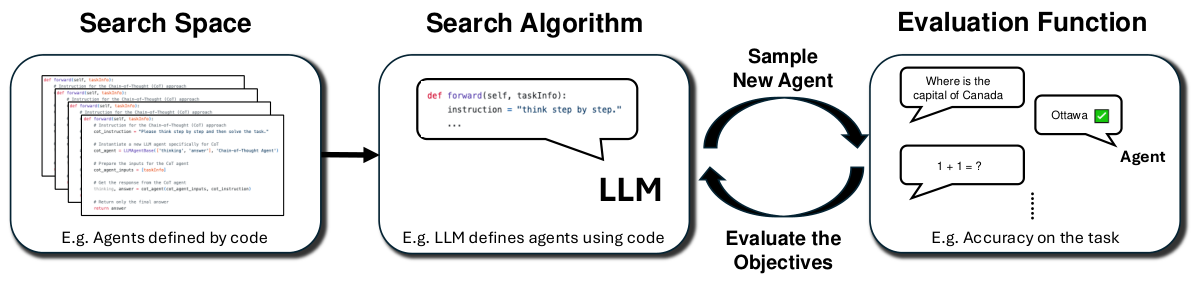
For example, ProTeGi uses one model call to generate critiques from incorrect answers and another to rewrite instructions using those critiques. A further search procedure evaluates multiple instruction candidates and retains some for the next iteration. Being able to write candidates is not the same capability as finding good candidates within a limited budget (Pryzant et al. 2023).
GEPA does more than edit instructions from execution records. It selects candidates to edit by exploiting their differing strengths on individual validation inputs. DGM maintains a collection of evaluated code candidates. Neither is adequately described as a single instruction asking a model to “improve this” (Agrawal et al. 2026; Jenny Zhang et al. 2026).
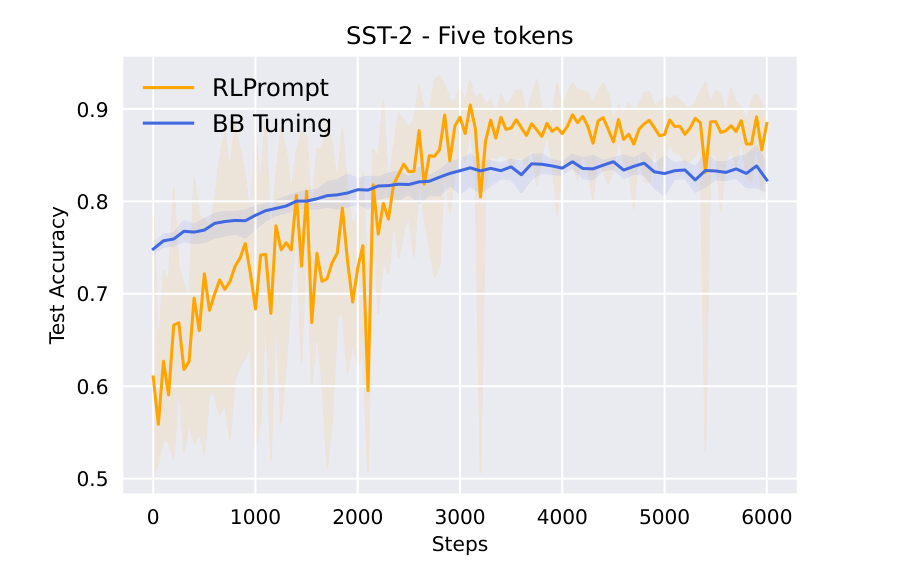
The optimizer must also be distinguished from the target model. RLPrompt learns a policy that generates discrete prompts for a fixed target model. Thus, research that leaves target-model weights unchanged can still train the candidate generator’s weights (Deng et al. 2022). Figure 3 shows how the resulting prompts’ test accuracy changes while the generation policy is trained. Using reinforcement learning does not, by itself, mean that the target model is trained.
Five Questions for Comparing Research
Each chapter uses the same questions.
- What changes? Instructions, demonstrations, call structure, code, or memory? What stays fixed?
- What informs the next candidate? What information is provided: final scores, incorrect answers, critiques, intermediate execution records, or past candidates?
- How are candidates searched and selected? Are candidates enumerated at once, edited locally over successive steps, or maintained in multiple lineages?
- What is learned? Are only histories and candidates updated, or do the candidate generator’s or target model’s weights also change?
- What do the experiments support? Do they measure the final configuration’s performance, search efficiency, generalization to unseen inputs, or transfer to another model?
These questions are not intended to place every study in one ranking. Reported scores cannot be directly compared when target models, initial configurations, editing permissions, and evaluation budgets differ. Prioritize controlled comparisons and ablations within the same paper, asking which design effects they isolate.
Scope and How to Read the Literature
The book begins with prompt generation and evaluation, then broadens to joint optimization of fixed modules, search over call structures and code, experience reuse, and learned optimizers. This order is not a historical claim that later work uniformly replaced earlier work. It shows how making different components editable creates different research problems.
The focus is on accepted papers at major conferences and in peer-reviewed journals, including Findings. Workshop papers, work with only author-reported acceptance, and preprints without confirmed official acceptance are explicitly identified as such. The status check is as of October 2026. The existence of new research should not be confused with cross-field consensus.
Adding memory, reflecting on each answer, and training the target model can all contribute to improvement. They differ, however, in what accumulates and which inputs are used for evaluation. This is why Reflexion’s retries on the same problem are distinguished from ExpeL’s use of experience across tasks (Shinn et al. 2023; Zhao et al. 2024).
Finally, the book examines performance on unseen inputs, search and execution costs, and comparisons of optimizers themselves. External evaluation and data splits are treated not as defining conditions for this research, but as ways to assess how far improvement claims can be trusted. The goal is not to memorize method names. It is to be able to explain what changed, why it changed, and what the experiments established when reading a new paper.
Figure Credits
Figure 1: (S. Zhang et al. 2024). Original: published version, Figure 1. © The authors. CC BY 4.0. Surrounding margins cropped and figure rasterized, with no content changes.
Figure 2: (Hu et al. 2025). Original: published version, Figure 2. © The authors. CC BY 4.0. Cropped and rasterized.
Figure 2: (Deng et al. 2022). Original: published version, Figure 2. CC BY 4.0. Cropped and rasterized.